Remember when AI-generated images couldn’t spell their way out of a paper bag? You’d ask for a poster that said “Happy Birthday Sarah” and end up with something that looked more like “Hapyp Bitrdhay Sahar” scrawled in a haunted font. Well, that era is pretty much over. OpenAI just dropped ChatGPT Images 2.0 on April 21, 2026, and honestly? It’s making me rethink how I approach a lot of creative work.
Here’s the thing, we’ve had image models for years now. DALL-E, Midjourney, Stable Diffusion, Nano Banana, Flux, Grok Imagine, you name it. Each one was better than the last at photorealism, at style transfer, at making pretty pictures. But none of them really cracked the hard stuff: readable text, multi-panel layouts, infographics that actually make sense, full pages of design with consistent branding. That’s the wall ChatGPT Images 2.0 appears to have finally punched through.
Let me walk you through what’s real, what’s marketing, and whether it’s actually worth your time.
So What Exactly Is ChatGPT Images 2.0?
ChatGPT Images 2.0 is OpenAI’s brand new image generation model — the successor to GPT Image 1.5 (which itself replaced the original DALL-E-powered image system back in March 2025). Under the hood, it’s officially called gpt-image-2, and it’s rolling out globally right now to ChatGPT and Codex users, with the more powerful Thinking mode reserved for Plus, Pro, Business, and Enterprise subscribers.
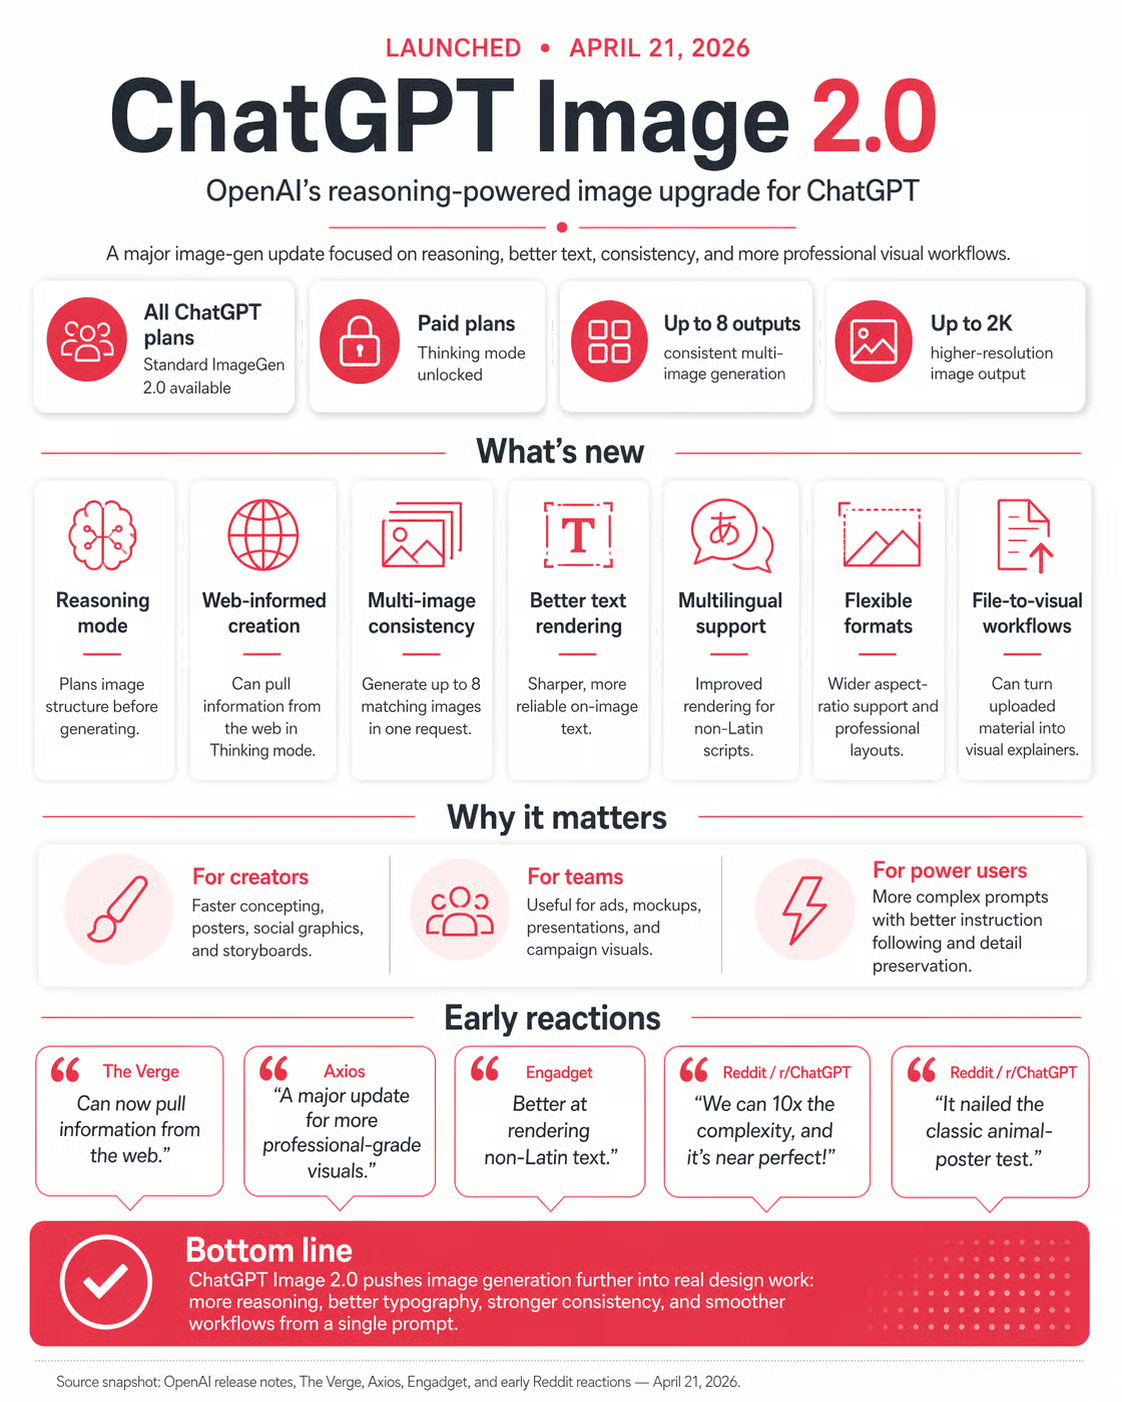
The short version? This is the first image model from OpenAI that actually reasons before it draws. It can search the web. It can pull in real-time data. It can produce up to eight different images from a single prompt while keeping the same characters and objects consistent across all of them. And this is the kicker it can render legible, accurate text inside images, including in Japanese, Korean, Chinese, Hindi, and Bengali.
OpenAI is pitching it as something bigger than a prettier DALL-E. In their own words, they want users to stop thinking about image generation as “decoration” and start treating it as a language — a way to explain ideas, teach concepts, and make visual arguments. That’s ambitious framing, but after a few days of hands-on testing, I kinda get it.
What’s Actually New? The Real Feature Breakdown
Let me skip the corporate talking points and give you the things that actually matter when you use it.
1. Text Rendering That Doesn’t Embarrass You
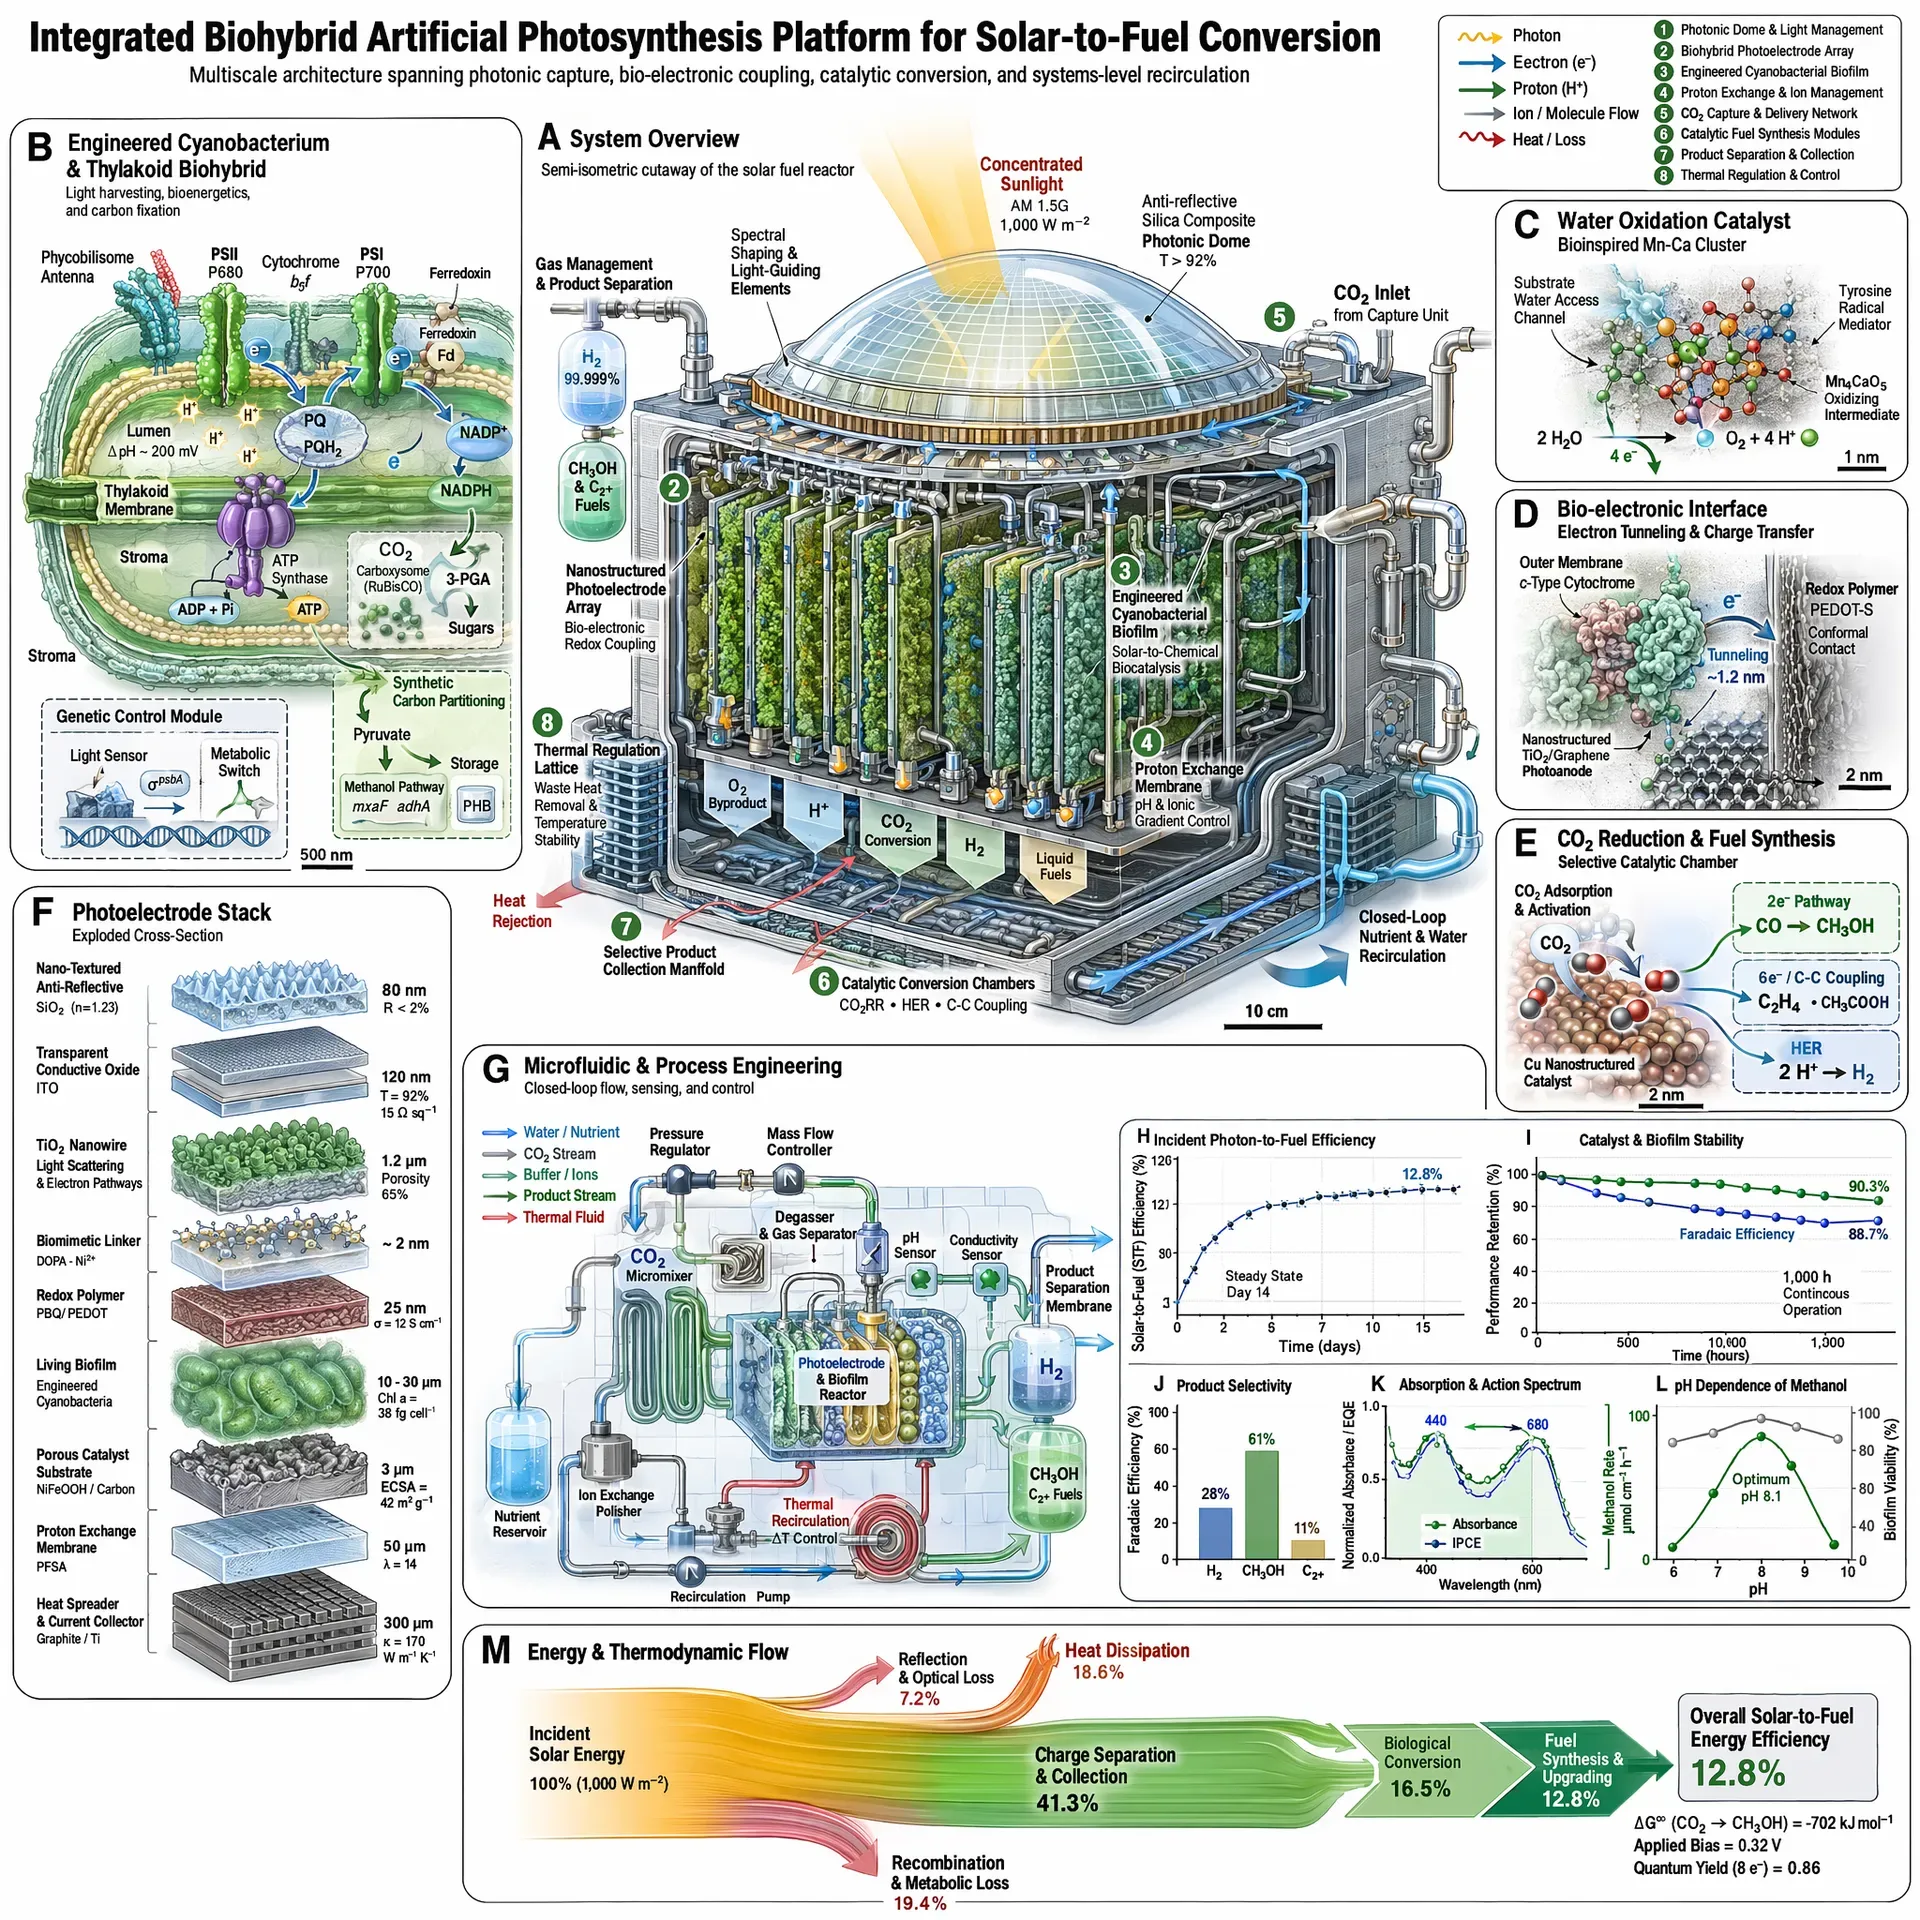
This is the headline feature, and it deserves to be. For the first time, ChatGPT can reliably generate images where text is — wait for it — spelled correctly. Early testers are reporting near 99% accuracy on text rendering, which is a dramatic jump from where we were even six months ago.
You can now make a magazine cover with a full table of contents. A product mockup with actual legible feature bullets. A meme with a caption that doesn’t require manual Photoshop cleanup. This single improvement unlocks about half the use cases designers have been begging for since 2023.
2. Reasoning and Web Search Before It Draws
Here’s where things get interesting. Images 2.0 taps into ChatGPT’s reasoning engine, which means when you give it a prompt, it can actually think about what should go in the image — even searching the internet for current info if needed.
The example Wired ran was perfect: they asked for “an infographic with San Francisco’s weather forecast for tomorrow and activities worth doing.” Images 2.0 pulled actual weather data, matched it to weather-appropriate activities, and drew recognizable versions of the Ferry Building, Castro Theater, Painted Ladies, and Transamerica Pyramid. That’s not an image generator — that’s a visual researcher.
The ChatGPT Images 2.0 knowledge cutoff is now December 2025, which is the latest among OpenAI’s public models.
3. Multiple Images From a Single Prompt (With Continuity)
In Thinking mode, Images 2.0 can generate up to eight images from one prompt and keep the characters, objects, and style consistent across all of them.
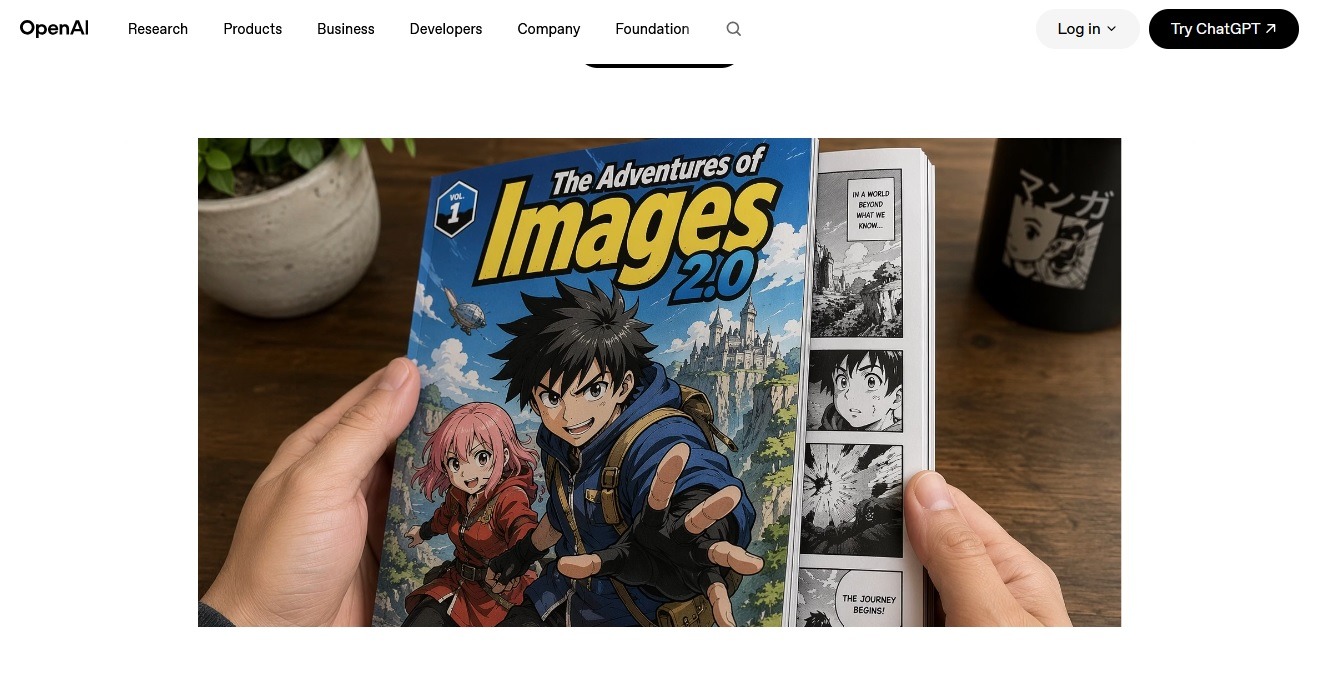
This is enormous for anyone making storyboards, children’s books, manga pages, product catalogs, or character sheets. You can now ask for “a character named Kenji in five different poses” and actually get Kenji — not five different guys who all vaguely resemble Kenji.
4. Multilingual Text – Including Non-Latin Scripts
OpenAI put serious work into making non-English text rendering viable. Japanese, Korean, Chinese, Hindi, and Bengali are now supported with what they call “significant gains” in accuracy.
I should be honest, though — this isn’t flawless. Wired’s tester asked Images 2.0 to make a Chinese fan-style Timothée Chalamet poster, and the AI itself admitted afterward that “a lot of it is fake, or semi-gibberish AI text dressed up to look like Chinese.” So if you’re rendering East Asian scripts for production work, double-check with a native speaker before publishing.
5. Flexible Aspect Ratios (Finally)
Anyone who’s fought with DALL-E to get a banner-width image knows the pain. Images 2.0 now supports aspect ratios from 3:1 wide to 1:3 tall, with size adjustments built directly into the prompt. No more workarounds. No more “sure, I made a square even though you asked for widescreen.”
6. Higher Fidelity and 2K Resolution
The model supports outputs up to 2K resolution, with more accurate small-text handling, better UI element generation, and tighter control over stylistic constraints. For anyone producing web graphics, social media assets, or print materials, this is the kind of quality jump that actually saves you a round-trip to Photoshop.
7. The “Visual Thought Partner” Vibe
OK, the language gets a little flowery here, but the underlying shift is real. Instead of feeding Images 2.0 a pixel-perfect prompt, you can now give it a concept — like “make a study guide for my Spanish exam tomorrow” — and it’ll build structured, multi-page visuals with continuity. That’s a fundamentally different kind of tool than we had a month ago.
ChatGPT Images 2.0 vs. The Old Version: What’s Different
Since a lot of people are coming into this having used GPT Image 1 or 1.5, here’s how the two stack up:
| Feature | GPT Image 1.5 | ChatGPT Images 2.0 |
|---|---|---|
| Text rendering accuracy | Solid for short text, struggles with paragraphs | Near 99% in English; strong in JA/KO/ZH/HI/BN |
| Reasoning before generation | ❌ | ✅ Thinking mode |
| Web search integration | ❌ | ✅ Pulls real-time info |
| Multi-image from single prompt | Limited | Up to 8 with character continuity |
| Max resolution | ~1K standard | Up to 2K |
| Aspect ratio flexibility | Limited | 3:1 to 1:3 |
| Knowledge cutoff | Older | December 2025 |
| API model name | gpt-image-1.5 | gpt-image-2 |
| Designed for | Single image outputs | Multi-page, multi-panel compositions |
If you’ve been using Image 1.5 and wondering whether the upgrade is worth it — yes, if you care about text, layouts, or multi-asset projects. If you’re only generating single illustrations and portraits, the leap is smaller (though still noticeable in detail quality).
Pricing: What It’ll Actually Cost You
Let’s talk money. This is where things get a bit more complicated than OpenAI’s announcement makes it sound.
For consumers (ChatGPT users):
- Free tier: Access to the base Images 2.0 model
- ChatGPT Go ($8/mo): Higher quotas
- ChatGPT Plus ($20/mo): Access to Thinking mode
- ChatGPT Pro ($200/mo): “More advanced image generation” — though OpenAI has been vague about exactly what that means (higher limits? Higher quality? Both?)
For developers (API access):
| Type | Input | Cached Input | Output |
|---|---|---|---|
| Image | $8.00 | $2.00 | $30.00 |
| Text | $5.00 | $1.25 | $10.00 |
(Prices per 1M tokens / standard billing unit) OpenAI Pricing
Those output costs for image generation — $30 per million tokens — are not cheap. If you’re thinking of using Images 2.0 at scale for a product, budget carefully. The consumer tier is a much better deal for most people.
The Hype vs. The Reality: What Actually Works
Here’s where I put my skeptic hat on. Tech launches always get the PR treatment. Let me tell you what genuinely impressed me and what didn’t.
What Actually Works
- Infographics are suddenly trivial. I generated a 3-panel educational infographic about the water cycle for my nephew’s homework in about 20 seconds. It had labels, arrows, a legend, and was actually readable. Try doing that in Canva in 20 seconds.
- Character consistency across panels. I asked for a four-panel comic featuring a character named Luca. All four panels had the same Luca. Same hair, same jacket, same vibe. This used to require Photoshop voodoo or careful seed management. Now it just… works.
- Historical maps and data visualizations. One VentureBeat tester had it generate a map showing the peak extents of the Aztec, Maya, and Inca empires with a legible legend. Only one other model (Nano Banana 2) can reliably do that.
- Magazine/poster layouts. A fake magazine cover I generated had full headlines, volume numbers, a legible barcode with a “Display Until” date, and professionally aligned columns of body text. That used to be a 2-hour Figma job.
- UI screenshots and fake product mockups. Images 2.0 nails this. You can generate believable-looking app interfaces with working button labels, menu text, and proper spacing. Designers making case-study mockups are going to have a field day.
What Doesn’t (Yet)
- Brand fidelity is shaky. ZDNET’s David Gewirtz tested it with the ZDNET logo, and it just… refused to get it right. It gave him a droopy “Z,” then found an old logo from before their 2022 redesign, then added a rudder shape to the “D.” This is a common failure mode across all current image models, but it’s worth knowing.
- Non-English text has edge cases. As Wired found, Chinese and other non-Latin scripts can devolve into plausible-looking gibberish if the prompt is complex. OpenAI acknowledges this is a work in progress.
- Thinking mode is slower. Much slower. Because it reasons and searches the web before generating, expect to wait longer for each image. That’s the trade-off — quality for speed.
- The tier structure is confusing. OpenAI still hasn’t clearly spelled out what Pro subscribers get over Plus subscribers beyond “more advanced outputs.” If you’re considering the $200/month jump, wait for clarity.
- Artistic flair vs. Midjourney. Let’s be honest — Images 2.0 is incredibly capable, but it doesn’t have the raw aesthetic punch of Midjourney V7 on pure art prompts. If you want painterly, dreamy, cinematic outputs for wall art, Midjourney still has an edge.
How Does It Compare to Nano Banana 2 and Midjourney?
Quick honest rundown:
ChatGPT Images 2.0 wins at: Text-heavy compositions, infographics, multi-panel storytelling, reasoning-based image generation (where the model needs to look things up), UI mockups, and mixed text-and-visual documents like posters and magazines.
Google’s Nano Banana 2 wins at: Photorealistic editing, quick figurine-style renders (the meme trend that blew up last year), and raw speed. It’s the better choice if you want to transform yourself into a Pixar character for Instagram.
Midjourney wins at: Pure artistic output. Cinematic lighting, painterly textures, dreamy aesthetics. For fine-art-style work or moody concept design, nothing touches it yet.
Flux 2 Pro wins at: Commercial photorealism and production-grade assets. If you’re making product shots or fashion editorials, Flux is quietly excellent. You can view the Reddit discussion Compare ChatGPT Image 2.0 vs Gemini Nano Banana Pro.
The honest takeaway? No single model wins everything in 2026. Serious creators are using multiple tools for different tasks. Images 2.0 is now the top pick for anything involving text, layouts, or reasoning. For art and photorealism, the competition is still fierce.
Practical Tips For Getting Great Results
From experience with the tool over the past few days, here’s what’s already delivering consistent wins:
Describe the goal, not the pixels. Instead of “a blue rectangle with white text that says Sale 50% Off,” try “a high-converting sale banner for a luxury handbag brand, confident and minimalist.” The reasoning engine does the translation.
Use Thinking mode for anything with multiple elements. If your output involves text + layout + multiple panels, Thinking mode is worth the wait. The base mode can do it, but the Thinking version is consistently better.
Upload reference images. Images 2.0 is substantially better at editing existing images than generating from scratch when brand fidelity matters. Upload your logo, upload your product shot, and ask it to build around those.
Ask for self-critique. You can literally ask “does anything in this image look wrong or off-brand?” and Images 2.0 will often catch its own mistakes. Then you can ask for a fix in the same conversation.
Batch with continuity. For any series work (characters, product variants, storyboards), request all the images in a single prompt to maintain consistency. Don’t chain multiple separate generations.
Specify aspect ratio early. Put it right at the start of the prompt: “Generate a 16:9 infographic…” It obeys much better when the ratio is front-loaded.
Remember the web search. For anything data-dependent — weather, stock prices, current events, recent facts — tell it to pull fresh info. That’s what separates Images 2.0 from every other generator on the market.
Who Should Actually Use ChatGPT Images 2.0?
Not every tool is for every person. Here’s who’s going to love this:
- Content creators making thumbnails, infographics, educational content, and visual explainers — especially if you’ve been gluing together screenshots and Canva designs.
- Marketers needing fast ad creative with real text, product mockups, campaign visuals, and A/B variations.
- Designers who want a rough draft before they open Figma, or who need quick concept exploration.
- Teachers and educators building study guides, lecture slides, and visual explanations.
- Writers and bloggers (hi) creating blog headers, featured images, and illustrated guides.
- Indie developers mocking up UI designs, app store assets, and landing page visuals.
- Anyone learning a non-English language who wants visual flashcards and culturally accurate learning material.
Who should wait? If your work lives and dies by brand fidelity (agency designers, corporate marketing teams), keep treating Images 2.0 as a first-draft tool rather than a production-asset tool. You’ll still need human cleanup.
What Most People Get Wrong About Images 2.0
Here’s where I’ll get opinionated for a second. Most of the hype framing I’m seeing online is “ChatGPT Images 2.0 replaces designers.” That’s wrong, and it’s also embarrassingly wrong.
What Images 2.0 actually does is collapse the distance between an idea and a visual draft. That’s a huge deal — it doesn’t replace design taste, compositional skill, or brand thinking. It replaces the grunt work of going from zero to a rough visual. Which means a designer using Images 2.0 well will probably do 3-5x more work in the same amount of time, not get replaced.
What most people don’t realize is that the real breakthrough isn’t the pretty outputs — it’s the reasoning integration. For the first time, you can ask an image model to solve a problem, not just draw a scene. That opens up a whole new category of use cases: personalized educational content, real-time data visualizations, research-backed infographics, dynamic marketing assets. That’s the part that’s genuinely new, and it’s the part most reviewers are underselling.
Final Verdict: Is It Worth the Hype?
Here’s my honest take after genuinely living with ChatGPT Images 2.0: Yes, it’s worth the hype, but probably not for the reasons the headlines emphasize.
It’s not worth the hype because it makes the prettiest pictures. (Midjourney still wins on pure aesthetics.) It’s not worth the hype because it’s cheap. (At scale, the API gets expensive.) It’s not worth the hype because it’s perfect. (It still hallucinates logos and stumbles on complex non-Latin text.)
It’s worth the hype because, for the first time in this whole AI boom, an image model is actually useful for the kind of messy, real-world design work that knowledge workers do every single day. The kind of work where you need legible text, consistent characters, accurate data, and flexible layouts. That category of tool basically didn’t exist a week ago. Now it does.
If you’re on ChatGPT Plus, you already have access — just flip on Thinking mode and go try it. If you’re on the free tier, you still get the base model, and it’s plenty capable for casual use. And if you’ve been holding out on paying for ChatGPT, this might be the feature that finally tips you over.
The AI industry will have moved on to something newer in six months — probably a Nano Banana 3 or an Adobe Firefly killer. But right now, ChatGPT Images 2.0 is the single most interesting image model for people who need AI to actually get work done. That’s a genuinely big deal.
Just don’t ask it to draw your company logo. It’ll get weird.
You May Also Like
 AI Tool Reviews
How to Use ChatGPT for Beginners: The Complete Step-by-Step Guide (2026)
 ChatGPT
How to Use ChatGPT at Work: Productivity Tips That Actually Save You Hours
 ChatGPT
How to Use ChatGPT Best Prompts
 AI Models
GPT-5.5 vs Claude Opus 4.7 vs Gemini 3.1 Pro: Real Benchmark Results Compared
 ChatGPT
 5.5 Is Here: Benchmarks, What’s New, What’s Different, and Is It Actually Worth the Hype?
 ChatGPT
